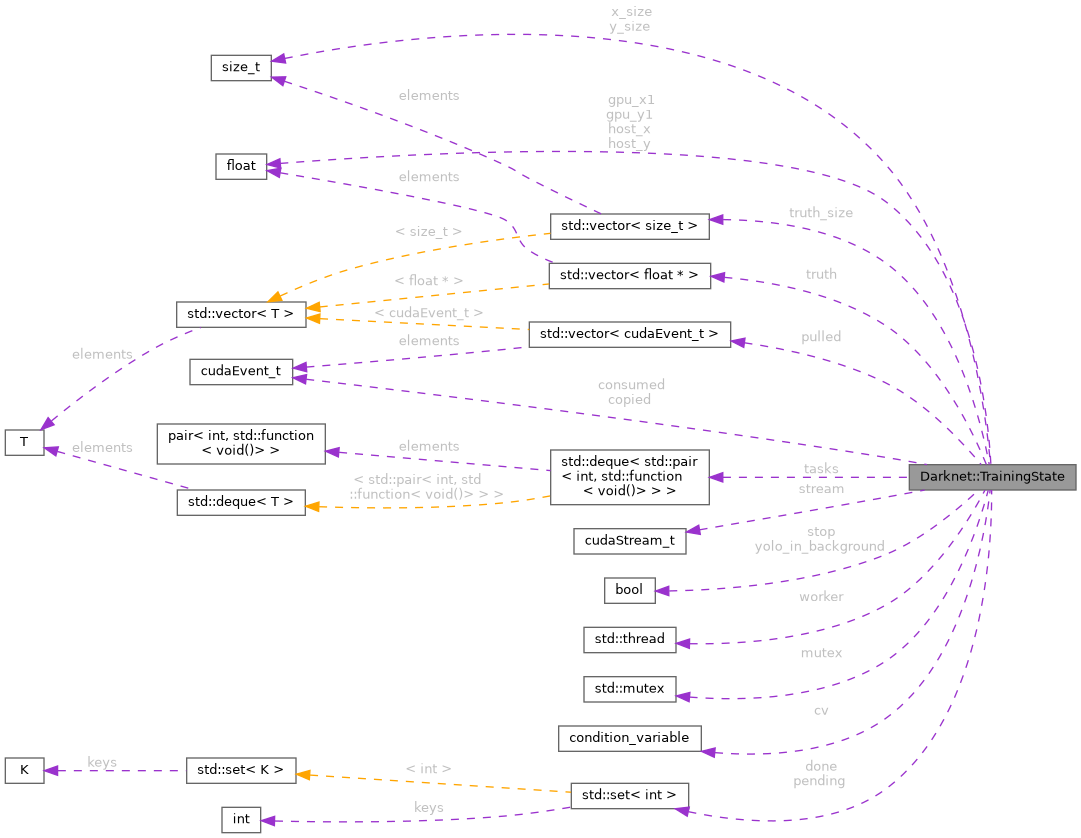
Things which belong to one network while it trains on a GPU:
More...
#include "darknet_network.hpp"
|
| cudaEvent_t | consumed [2] = {nullptr, nullptr} |
| | the GPU is done with the mini-batch in GPU buffer #k
|
| |
| cudaEvent_t | copied [2] = {nullptr, nullptr} |
| | the upload from host buffer #k is done
|
| |
| std::condition_variable | cv |
| |
| SInt | done |
| | layer indexes with a task which has finished
|
| |
| float * | gpu_x1 = nullptr |
| |
| float * | gpu_y1 = nullptr |
| |
| float * | host_x [2] = {nullptr, nullptr} |
| |
| float * | host_y [2] = {nullptr, nullptr} |
| |
| std::mutex | mutex |
| |
| SInt | pending |
| | layer indexes with a task, until wait_for_background_task()
|
| |
| bool | stop = false |
| |
| cudaStream_t | stream = nullptr |
| | used for the uploads
|
| |
| std::deque< std::pair< int, std::function< void()> > > | tasks |
| | layer index and task
|
| |
| std::thread | worker |
| |
| size_t | x_size = 0 |
| |
| size_t | y_size = 0 |
| |
| bool | yolo_in_background = false |
| | Whether the CPU part of the [yolo] layers runs on worker. Decided once for all the [yolo] layers.
|
| |
|
| std::vector< float * > | truth |
| | Per layer: pinned copy of the truths, and an event recorded once the outputs and truths are on the CPU.
|
| |
| std::vector< size_t > | truth_size |
| | Per layer: pinned copy of the truths, and an event recorded once the outputs and truths are on the CPU.
|
| |
| std::vector< cudaEvent_t > | pulled |
| | Per layer: pinned copy of the truths, and an event recorded once the outputs and truths are on the CPU.
|
| |
Things which belong to one network while it trains on a GPU:
- pinned host memory, a second GPU buffer, a CUDA stream and events which train_network_subdivisions_gpu() uses to upload the next mini-batch while the GPU works on the current one (GPU buffer #0 is the network's own
input_gpu and truth_gpu);
- a thread which computes the [yolo] deltas while the GPU continues, see start_background_task().
◆ consumed
| cudaEvent_t Darknet::TrainingState::consumed[2] = {nullptr, nullptr} |
the GPU is done with the mini-batch in GPU buffer #k
◆ copied
| cudaEvent_t Darknet::TrainingState::copied[2] = {nullptr, nullptr} |
the upload from host buffer #k is done
◆ cv
| std::condition_variable Darknet::TrainingState::cv |
◆ done
| SInt Darknet::TrainingState::done |
layer indexes with a task which has finished
◆ gpu_x1
| float* Darknet::TrainingState::gpu_x1 = nullptr |
◆ gpu_y1
| float* Darknet::TrainingState::gpu_y1 = nullptr |
◆ host_x
| float* Darknet::TrainingState::host_x[2] = {nullptr, nullptr} |
◆ host_y
| float* Darknet::TrainingState::host_y[2] = {nullptr, nullptr} |
◆ mutex
| std::mutex Darknet::TrainingState::mutex |
◆ pending
| SInt Darknet::TrainingState::pending |
◆ pulled
| std::vector<cudaEvent_t> Darknet::TrainingState::pulled |
Per layer: pinned copy of the truths, and an event recorded once the outputs and truths are on the CPU.
◆ stop
| bool Darknet::TrainingState::stop = false |
◆ stream
◆ tasks
| std::deque<std::pair<int, std::function<void()> > > Darknet::TrainingState::tasks |
◆ truth
| std::vector<float *> Darknet::TrainingState::truth |
Per layer: pinned copy of the truths, and an event recorded once the outputs and truths are on the CPU.
◆ truth_size
| std::vector<size_t> Darknet::TrainingState::truth_size |
Per layer: pinned copy of the truths, and an event recorded once the outputs and truths are on the CPU.
◆ worker
| std::thread Darknet::TrainingState::worker |
◆ x_size
| size_t Darknet::TrainingState::x_size = 0 |
◆ y_size
| size_t Darknet::TrainingState::y_size = 0 |
◆ yolo_in_background
| bool Darknet::TrainingState::yolo_in_background = false |
Whether the CPU part of the [yolo] layers runs on worker. Decided once for all the [yolo] layers.
The documentation for this struct was generated from the following file:


 1.9.8